I turned my job hunt into a pipeline in one night
Reading reposted LinkedIn listings to reach a no sponsorship line in paragraph six was not a plan. So one night I built JobPilot: fresh jobs from the source, scored and tailored while I slept.
-
40 minutes
from an empty Google Cloud project at 3:14 AM to a running pipeline and console, June 10
-
16 patterns
of citizenship, clearance and no sponsorship text that drop a job before any model sees it
-
7 sources
Greenhouse, Lever, Ashby, Hacker News, RemoteOK, Adzuna and LinkedIn, merged into one list
Key facts
- Problem
- Finding a job that would sponsor a visa meant reading reposted LinkedIn listings down to paragraph six.
- What I built
- A pipeline that reads company job boards, drops roles I could never take and tailors a resume per match.
- Outcome
- Used from the first morning; the pipeline ran 1,008 times before my copy stopped on October 8, 2026.
- Runs on
- A Cloud Run job with Gemini scoring, a Google Sheet as the database and a console behind sign in.
- Built
- On June 10, 2026, 40 minutes from an empty Google Cloud project to a running pipeline and console.
- Status
- Off since October 8, 2026; the code is public under MIT and a demo runs on fictional data.
The problem
I needed a job that would sponsor a visa, and LinkedIn made me find out the slow way. A posting says two weeks ago, it has been reposted twice, and paragraph six says the company cannot sponsor. I read all of it anyway, because that line could sit anywhere.
Recruiters run their side of hiring on an ATS with dashboards and automation. I was running mine on a browser tab and a spreadsheet I forgot to update. A job search is a pipeline, and I was doing every stage by hand.
What I built
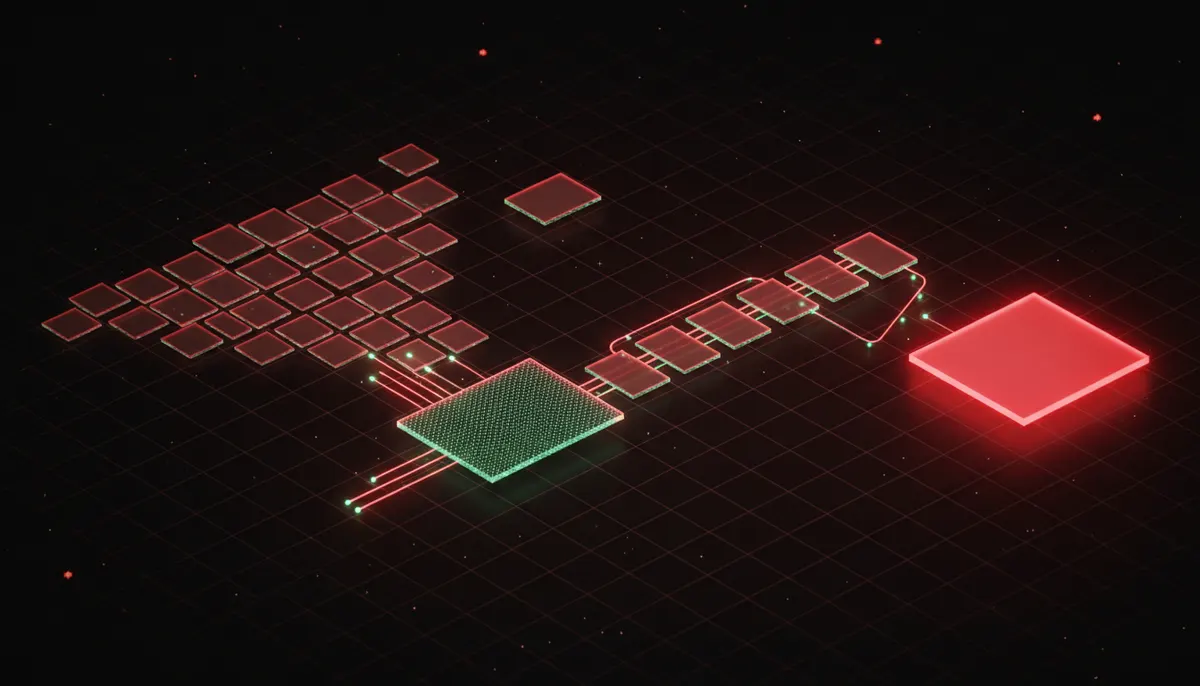
JobPilot reads companies’ own job boards, drops the postings I could never take, scores the rest against my profile with Gemini, and writes a tailored one page resume and cover letter for the good ones. A Google Sheet is the database. A small console behind Google sign in sits on top, and a digest email lists the best matches.
Open the drawing to see every part. This post is the first version. The full tour covers what it grew into.
The sprint
The first version took one evening, about five hours by my count. Google Cloud only saw the end. The project was created at 3:14 AM on June 10. The pipeline job existed three minutes later and ran for the first time at 3:25. The console went up at 3:54.
At 7:12 PM the same day the code went public on GitHub under MIT as JobPilot v1.0, with seven job sources and four resume variants. By midnight the pipeline had run 11 times. Two days later it was running every 30 minutes.
The hard parts
Resumes a parser could not read. My first PDFs came out of XeTeX. They looked perfect, and a text extractor read them as “New Y ork” and “T erraform”, which is what an ATS would see. Switching to pdflatex with the cmap package fixed the text layer. A check script now pulls the text out of the real PDF and fails any resume over one page or under 85 percent keyword coverage.
A Tailor button that ran everything. The console’s Tailor button was meant to start the job for one row. It started the whole pipeline. Cloud Run’s per run arguments replace a Dockerfile’s CMD, so mine were thrown away. Arguments added to an ENTRYPOINT append, so one line fixed it:
# Dockerfile
ENTRYPOINT ["python", "-m", "jobpilot"]
The cheapest filter goes first. Sixteen regex patterns drop citizenship, clearance and no sponsorship postings before any model sees them, and title words drop senior, staff, contract and intern roles. Whatever survives goes to Gemini in batches of 10. If the text still hints that sponsorship is unlikely, the scorer caps the fit at 10 and the row is rejected with a note.
What I said no to
Sending anything on its own. Outreach lands in Gmail drafts, and I press send. Reply tracking can move an application’s status forward and never overwrites an edit I made by hand.
A real database. The Sheet is free, I can filter it, and I can fix a row from my phone. For one person’s job hunt, a database server would be one more thing to run.
LinkedIn as the main source. It stays in, through an Apify actor capped at 50 results a run so it lives on free credits. The company boards carry the load. Greenhouse, Lever and Ashby publish their job boards through public APIs that need no key.
Where it landed
I used it from the first morning. In late June it settled into two runs each morning, and it ran 1,008 times before my copy stopped on October 8. The code stays public, and a demo of the console runs on fictional data.
I never measured hours saved or which interviews came from it, so I will not guess.
What I would keep: run the cheapest filter first, and let the machine write the drafts while I decide what gets sent.